ROC 曲线
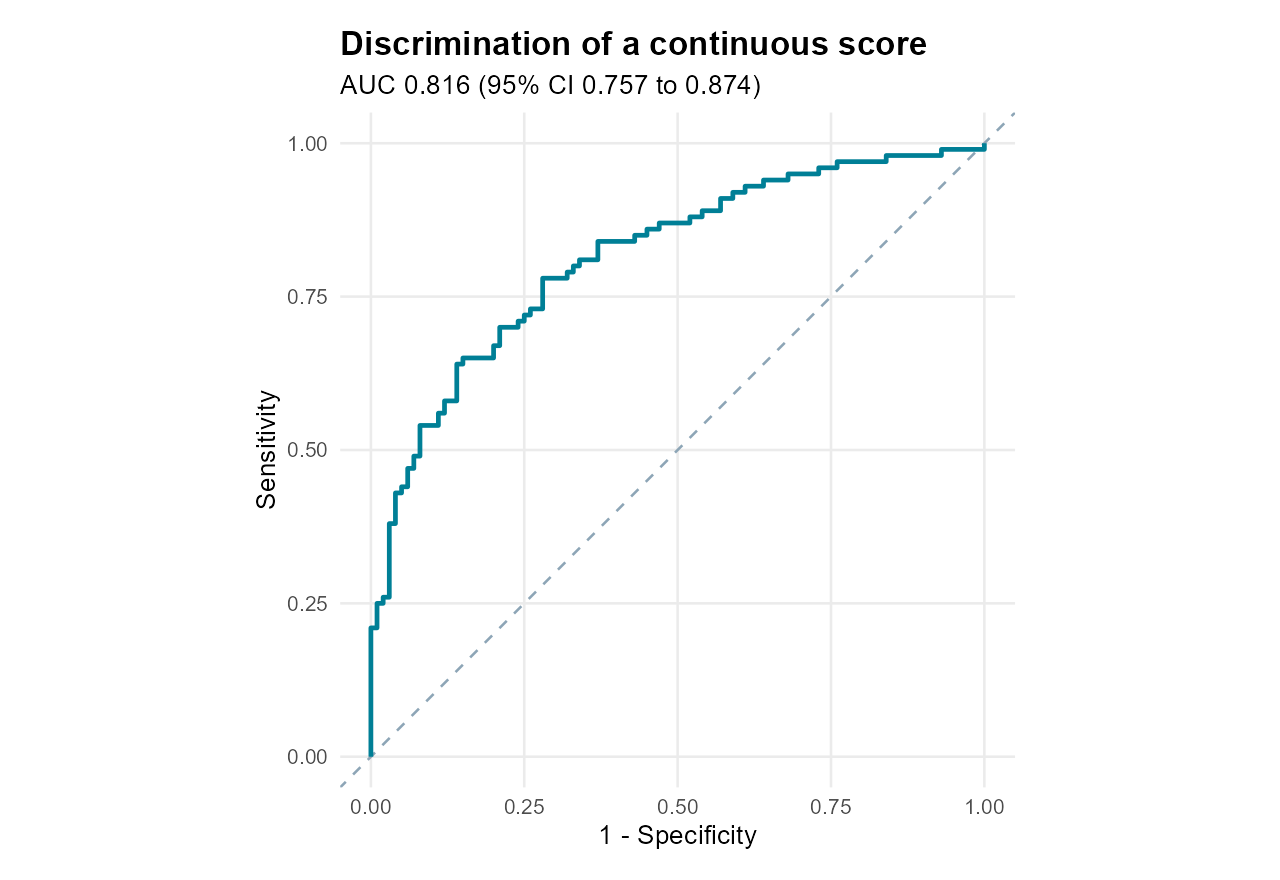
查看连续评分对二分类结局的判别表现。
准备怎样的数据?
每行一位独立受试者,包含真实类别和预测评分。
输入字段:id、outcome、score
完整 R 代码
所需包:ggplot2、jsonlite、pROC。首次使用时,先运行代码注释中的安装命令。
# ROC 曲线:单个连续评分的 ROC 与 AUC
# 项目原创脚本,MIT 许可;模拟数据 CC0-1.0;图形 CC BY 4.0。
# 在全新 R 会话运行。每次运行会更新下方 output_dir 中的本示例文件。
# 图形标签使用英文以避免不同电脑缺少中文字体;可在参数和 labs() 中修改。

# 1. 依赖:首次使用时手动运行以下安装命令,脚本不会自动安装。
# install.packages(c("ggplot2", "jsonlite", "pROC"))
required_packages <- c("ggplot2", "jsonlite", "pROC")
missing_packages <- required_packages[!vapply(required_packages, requireNamespace, logical(1), quietly = TRUE)]
if (length(missing_packages)) stop("Please install: ", paste(missing_packages, collapse = ", "))
library(ggplot2)

# 2. 可修改参数:颜色、字体、导出尺寸和路径。输出路径相对于当前工作目录。
set.seed(20261014)
colors <- c("#007F96", "#B66A46")
font_family <- "sans"
figure_width <- 8
figure_height <- 5.5
output_dir <- file.path(getwd(), "rfig-roc-output")
dir.create(output_dir, recursive = TRUE, showWarnings = FALSE)
theme_set(theme_minimal(base_size = 12, base_family = font_family) +
 theme(plot.background = element_rect(fill = "white", color = NA), panel.grid.minor = element_blank(),
       plot.title = element_text(face = "bold", size = 15), legend.position = "bottom",
       plot.margin = margin(14, 18, 14, 14)))

# 3. 示例数据:每行一位独立受试者,包含真实类别和预测评分。 替换 outcome 与 score,明确阳性类别和评分方向;真实模型优先用独立验证或合适的重采样预测。
# 使用自己的 CSV 时,将以下数据生成段替换为:
# data <- read.csv("your-data.csv", stringsAsFactors = FALSE)
# 再按本例要求设置分类顺序、检查字段、单位及缺失值。
data <- data.frame(id = 1:200, outcome = rep(c(0, 1), each = 100))
data$score <- rnorm(200, mean = 1.2 * data$outcome, sd = 1)
stopifnot(!anyNA(data))

# 4. 统计计算与绘图。阳性为 1,评分越高越倾向阳性;固定 levels=c(0,1)、direction="<",不自动翻转方向。AUC 为经验 ROC 曲线下面积,95% CI 使用 DeLong 方法。数据为演示评分;同一开发样本的表现不能替代独立验证,ROC 不评价校准。
roc <- pROC::roc(data$outcome, data$score, levels = c(0,1), direction = "<", quiet = TRUE)
auc <- as.numeric(pROC::auc(roc)); auc_ci <- as.numeric(pROC::ci.auc(roc, method = "delong"))
curve <- data.frame(fpr = 1 - roc$specificities, tpr = roc$sensitivities)
p <- ggplot(curve, aes(fpr, tpr)) + geom_abline(intercept = 0, slope = 1, linetype = "dashed", color = "#8DA5B6") +
 geom_path(color = colors[1], linewidth = 1) + coord_equal(xlim = c(0,1), ylim = c(0,1)) +
 labs(x = "1 - Specificity", y = "Sensitivity", title = "Discrimination of a continuous score", subtitle = sprintf("AUC %.3f (95%% CI %.3f to %.3f)", auc, auc_ci[1], auc_ci[3]))
metrics <- list(auc = auc, lower = auc_ci[1], upper = auc_ci[3])
print(p)

# 5. 导出:CSV 与绘图所用 data 完全一致,preview 与科研图片均来自同一个 p。
write.csv(data, file.path(output_dir, "data.csv"), row.names = FALSE, fileEncoding = "UTF-8")
ggsave(file.path(output_dir, "preview.png"), p, width = figure_width, height = figure_height, dpi = 160, bg = "white")
ggsave(file.path(output_dir, "figure.png"), p, width = figure_width, height = figure_height, dpi = 300, bg = "white")
ggsave(file.path(output_dir, "figure.pdf"), p, width = figure_width, height = figure_height, device = grDevices::pdf, bg = "white")
ggsave(file.path(output_dir, "figure.tiff"), p, width = figure_width, height = figure_height, dpi = 300, compression = "lzw", bg = "white")
jsonlite::write_json(metrics, file.path(output_dir, "metrics.json"), auto_unbox = TRUE, digits = 16, pretty = TRUE)
运行与修改
- 安装 R 和 RStudio,复制完整代码到新的 R 脚本文件,或打开下载的 .R 文件。
- 首次使用时,运行脚本顶部注释中的
install.packages()命令。 - 运行整个脚本。演示数据已包含在代码中,无需先下载 CSV。
- 图片和 CSV 保存在当前工作目录的
rfig-roc-output子目录。再次运行会更新其中的同名示例文件。
替换自己的数据
替换 outcome 与 score,明确阳性类别和评分方向;真实模型优先用独立验证或合适的重采样预测。
将脚本“示例数据”段替换为 data <- read.csv("your-data.csv", stringsAsFactors = FALSE),再按数据字典检查列名、类型、分类顺序及单位。演示 CSV 可用作结构参考。
调整外观与导出
在参数段修改颜色、字体、图片宽高和输出目录;在 labs() 中修改标题和轴标签。脚本提供 PDF、300 dpi PNG 和 LZW 压缩 TIFF 导出。演示图使用英文标签以减少字体依赖。
数据字典
下载示例 CSV每行一位独立受试者,包含真实类别和预测评分。 演示数据不含缺失值,使用固定种子 20261014。
| 列名 | 类型 | 单位 | 含义 | 角色 |
|---|---|---|---|---|
id | 整数 | 无 | 受试者编号 | 标识 |
outcome | 整数 | 无 | 0=阴性,1=阳性 | 真实类别 |
score | 数值 | 无 | 越高越倾向阳性 | 预测评分 |
统计说明与适用限制
阳性为 1,评分越高越倾向阳性;固定 levels=c(0,1)、direction="<",不自动翻转方向。AUC 为经验 ROC 曲线下面积,95% CI 使用 DeLong 方法。数据为演示评分;同一开发样本的表现不能替代独立验证,ROC 不评价校准。
本例用于展示绘图方法。应用于真实研究前,请结合研究设计、数据质量和模型假设选择统计方法。